Emoji semantics from descriptions and context
Leon Deng and I trained two sets of 300-dimensional emoji embeddings: one from official descriptions and another from the language surrounding emojis in tweets. The comparison reveals a useful tradeoff. Descriptions learn cleaner visual and literal relationships; tweets are noisier, but capture how meanings change through slang and online culture.
Two views of meaning
Useful embeddings let downstream systems treat related symbols similarly, which matters for tasks such as sentiment analysis and text classification. Earlier work including emoji2vec ↗ and Emojional ↗ built meaning primarily from descriptions and hand-selected related words. We wanted to test whether a lightweight model trained on naturally occurring context could adapt when online usage departed from an emoji’s literal definition.
The first model asks whether an emoji matches a short description such as “construction worker” or “distress signal.” We averaged pretrained FastText word vectors for each phrase, then learned an emoji vector whose dot product was high for matching descriptions and low for randomly sampled mismatches. This follows the central idea behind emoji2vec ↗, with FastText replacing word2vec so uncommon and out-of-vocabulary words still receive representations.
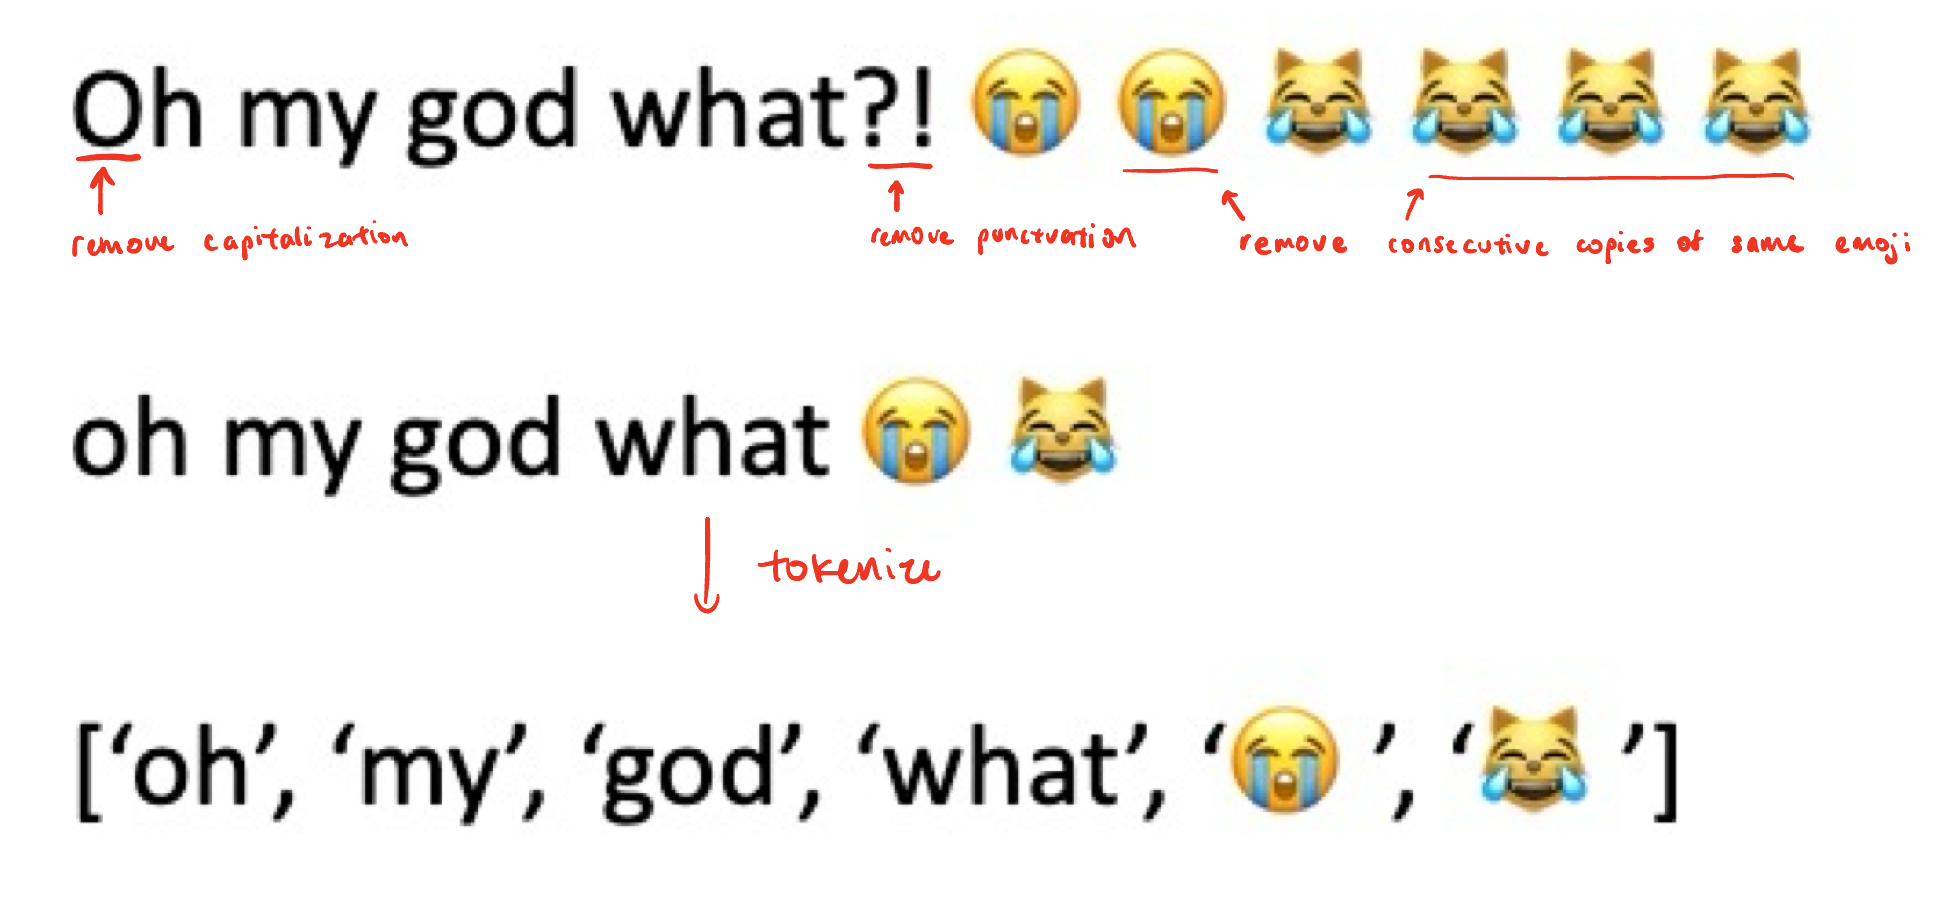
The second model learns from use rather than definitions. Inspired by emojiSpace ↗, we removed duplicates, numbers, hashtags, links, email addresses, and mentions from an emoji-tweet dataset. Each training example used a window of four tokens on either side of an emoji. The model then learned whether that emoji belonged with the surrounding words and emojis, in a setup similar to continuous bag-of-words.
Training setup
| Description model | Tweet model | |
|---|---|---|
| Training data | ~6,000 phrases · 1,661 emojis | ~272,000 contexts · 1,251 emojis |
| Examples per emoji | 250 positive · 250 negative | 250 positive · 250 negative |
| Train-test split | 80-20 | 80-20 |
| Training | 60 epochs · ~1 hour | 80 epochs · ~2 hours |
| Validation | 98% accuracy · 0.19 log loss | 79% accuracy · 0.39 log loss |
Both models used Adam with its default parameters. Positive examples were paired 1:1 with randomly sampled negative examples.
What the models learned
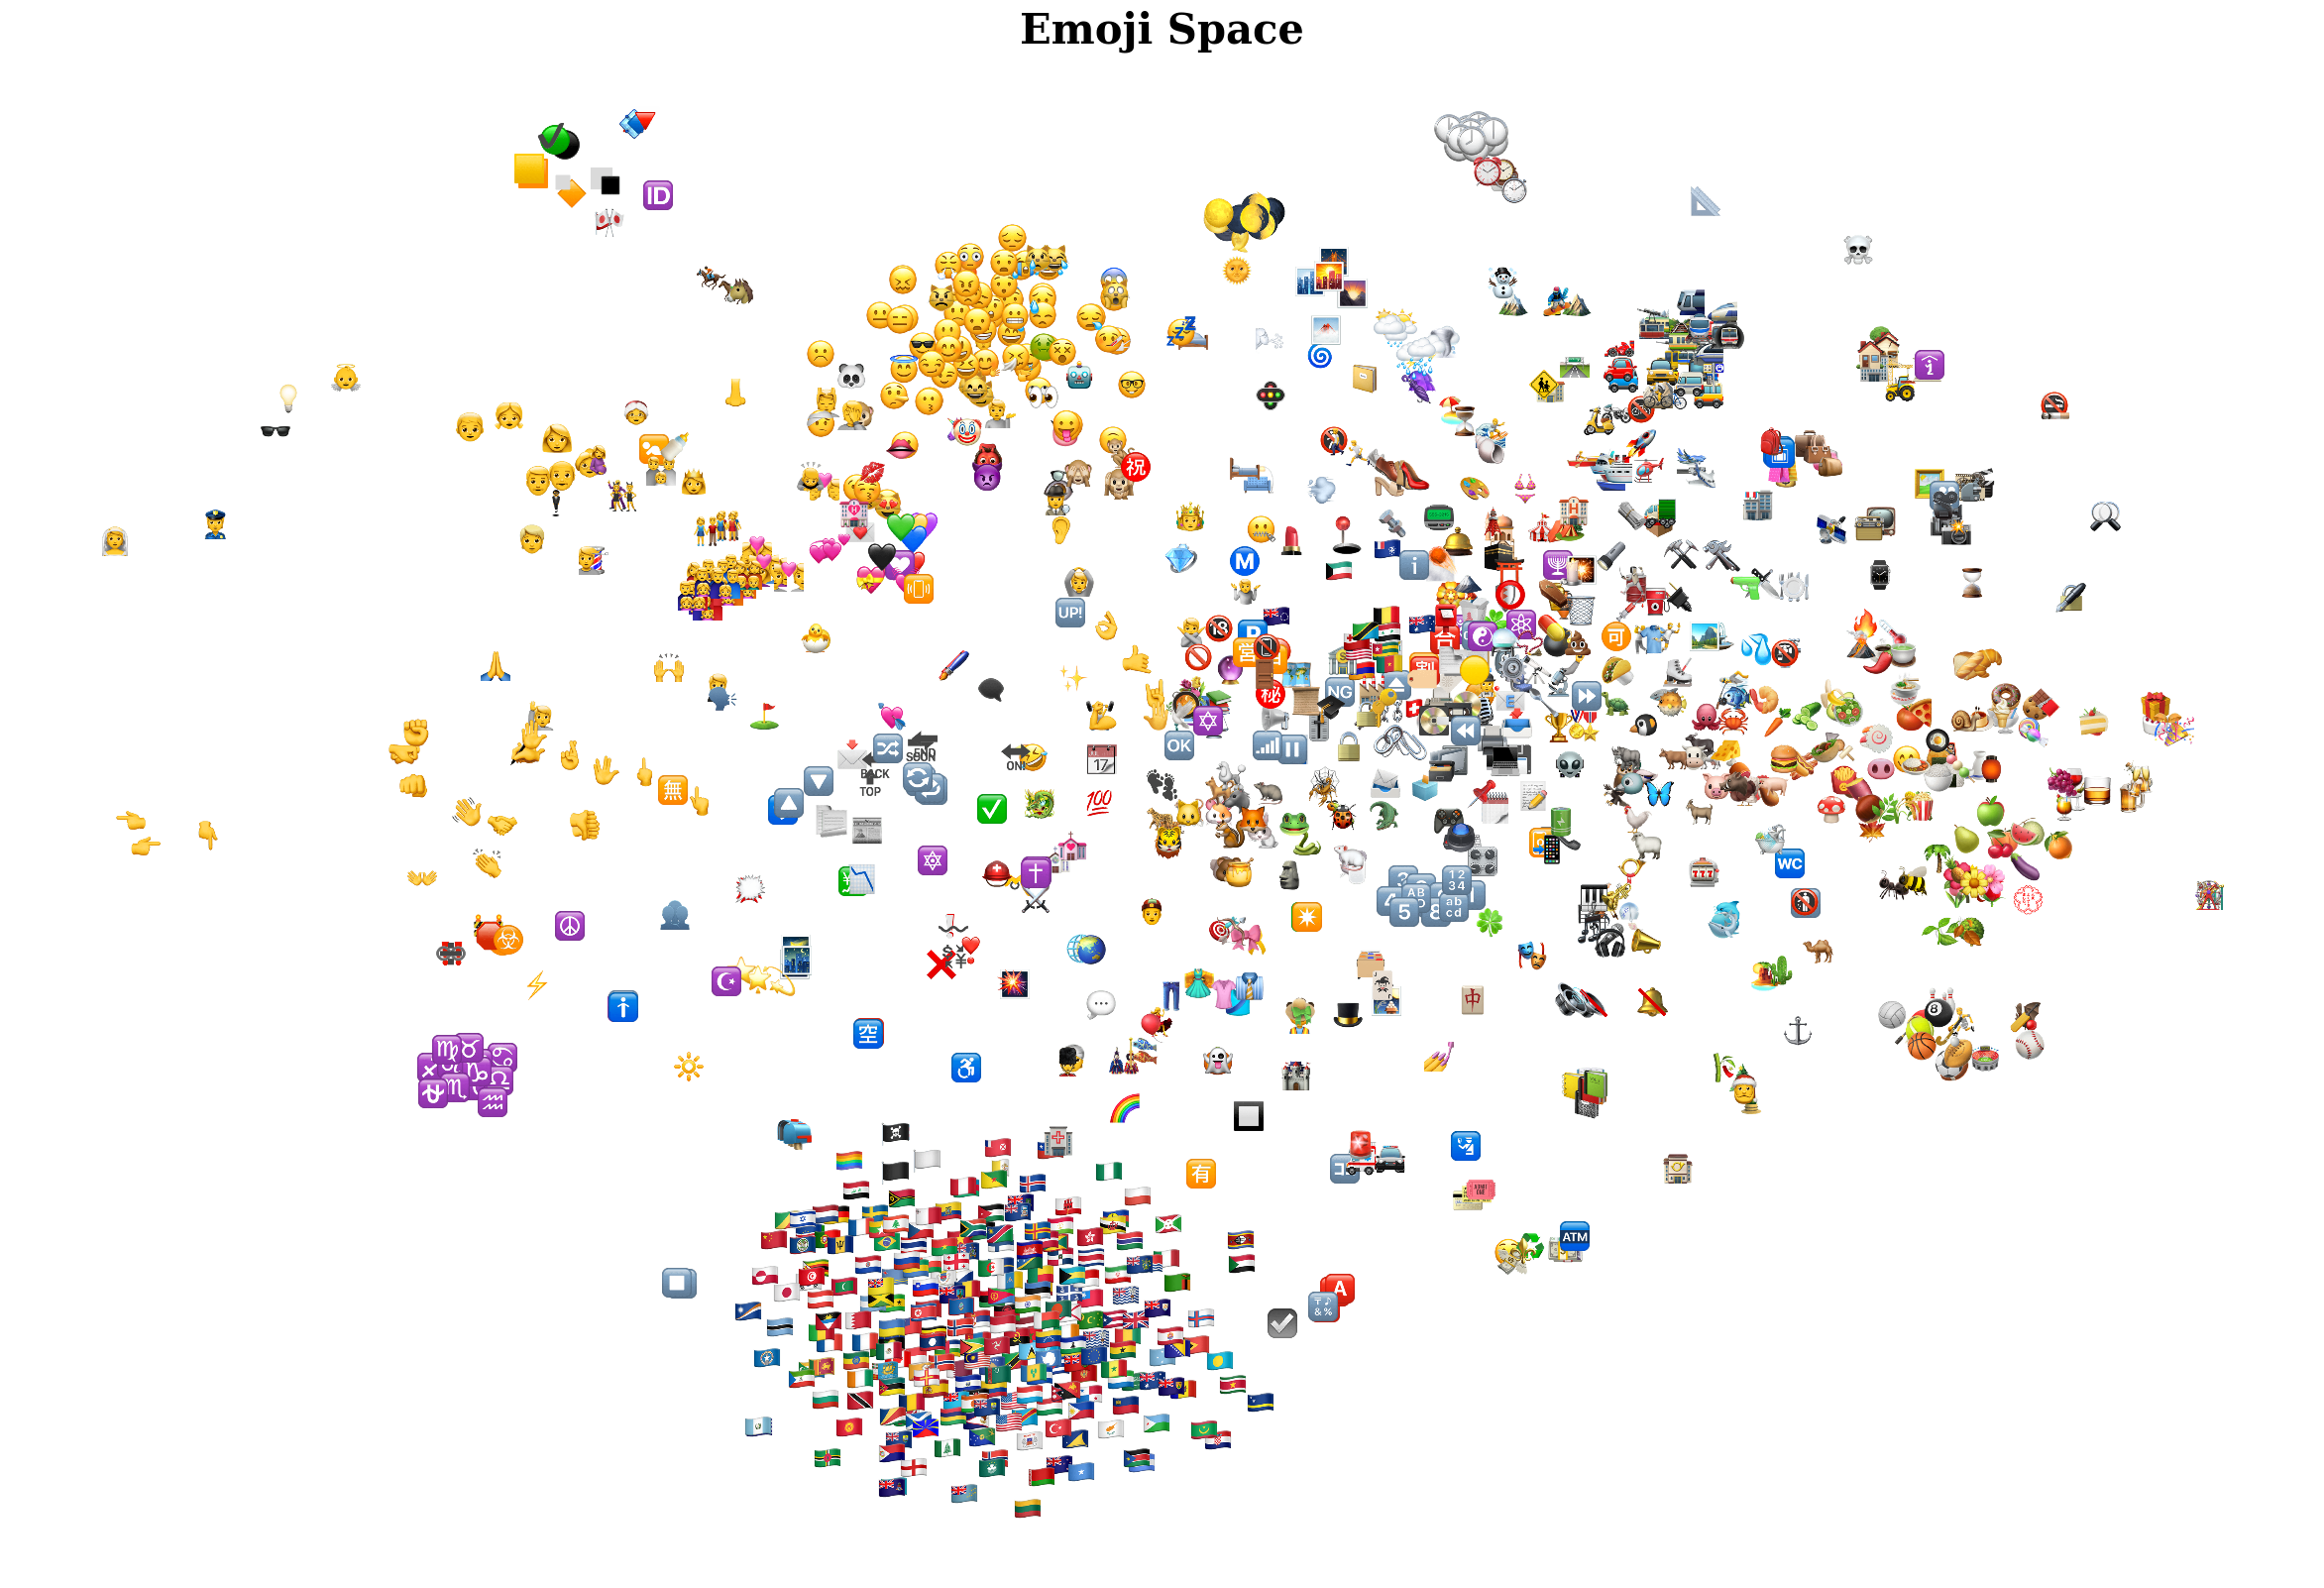
The description model produced the cleaner embedding space. After 60 epochs it reached 98% validation accuracy with 0.19 log loss. Faces, flags, food, vehicles, and zodiac symbols formed recognizable groups, and nearest neighbors usually shared an obvious literal meaning.
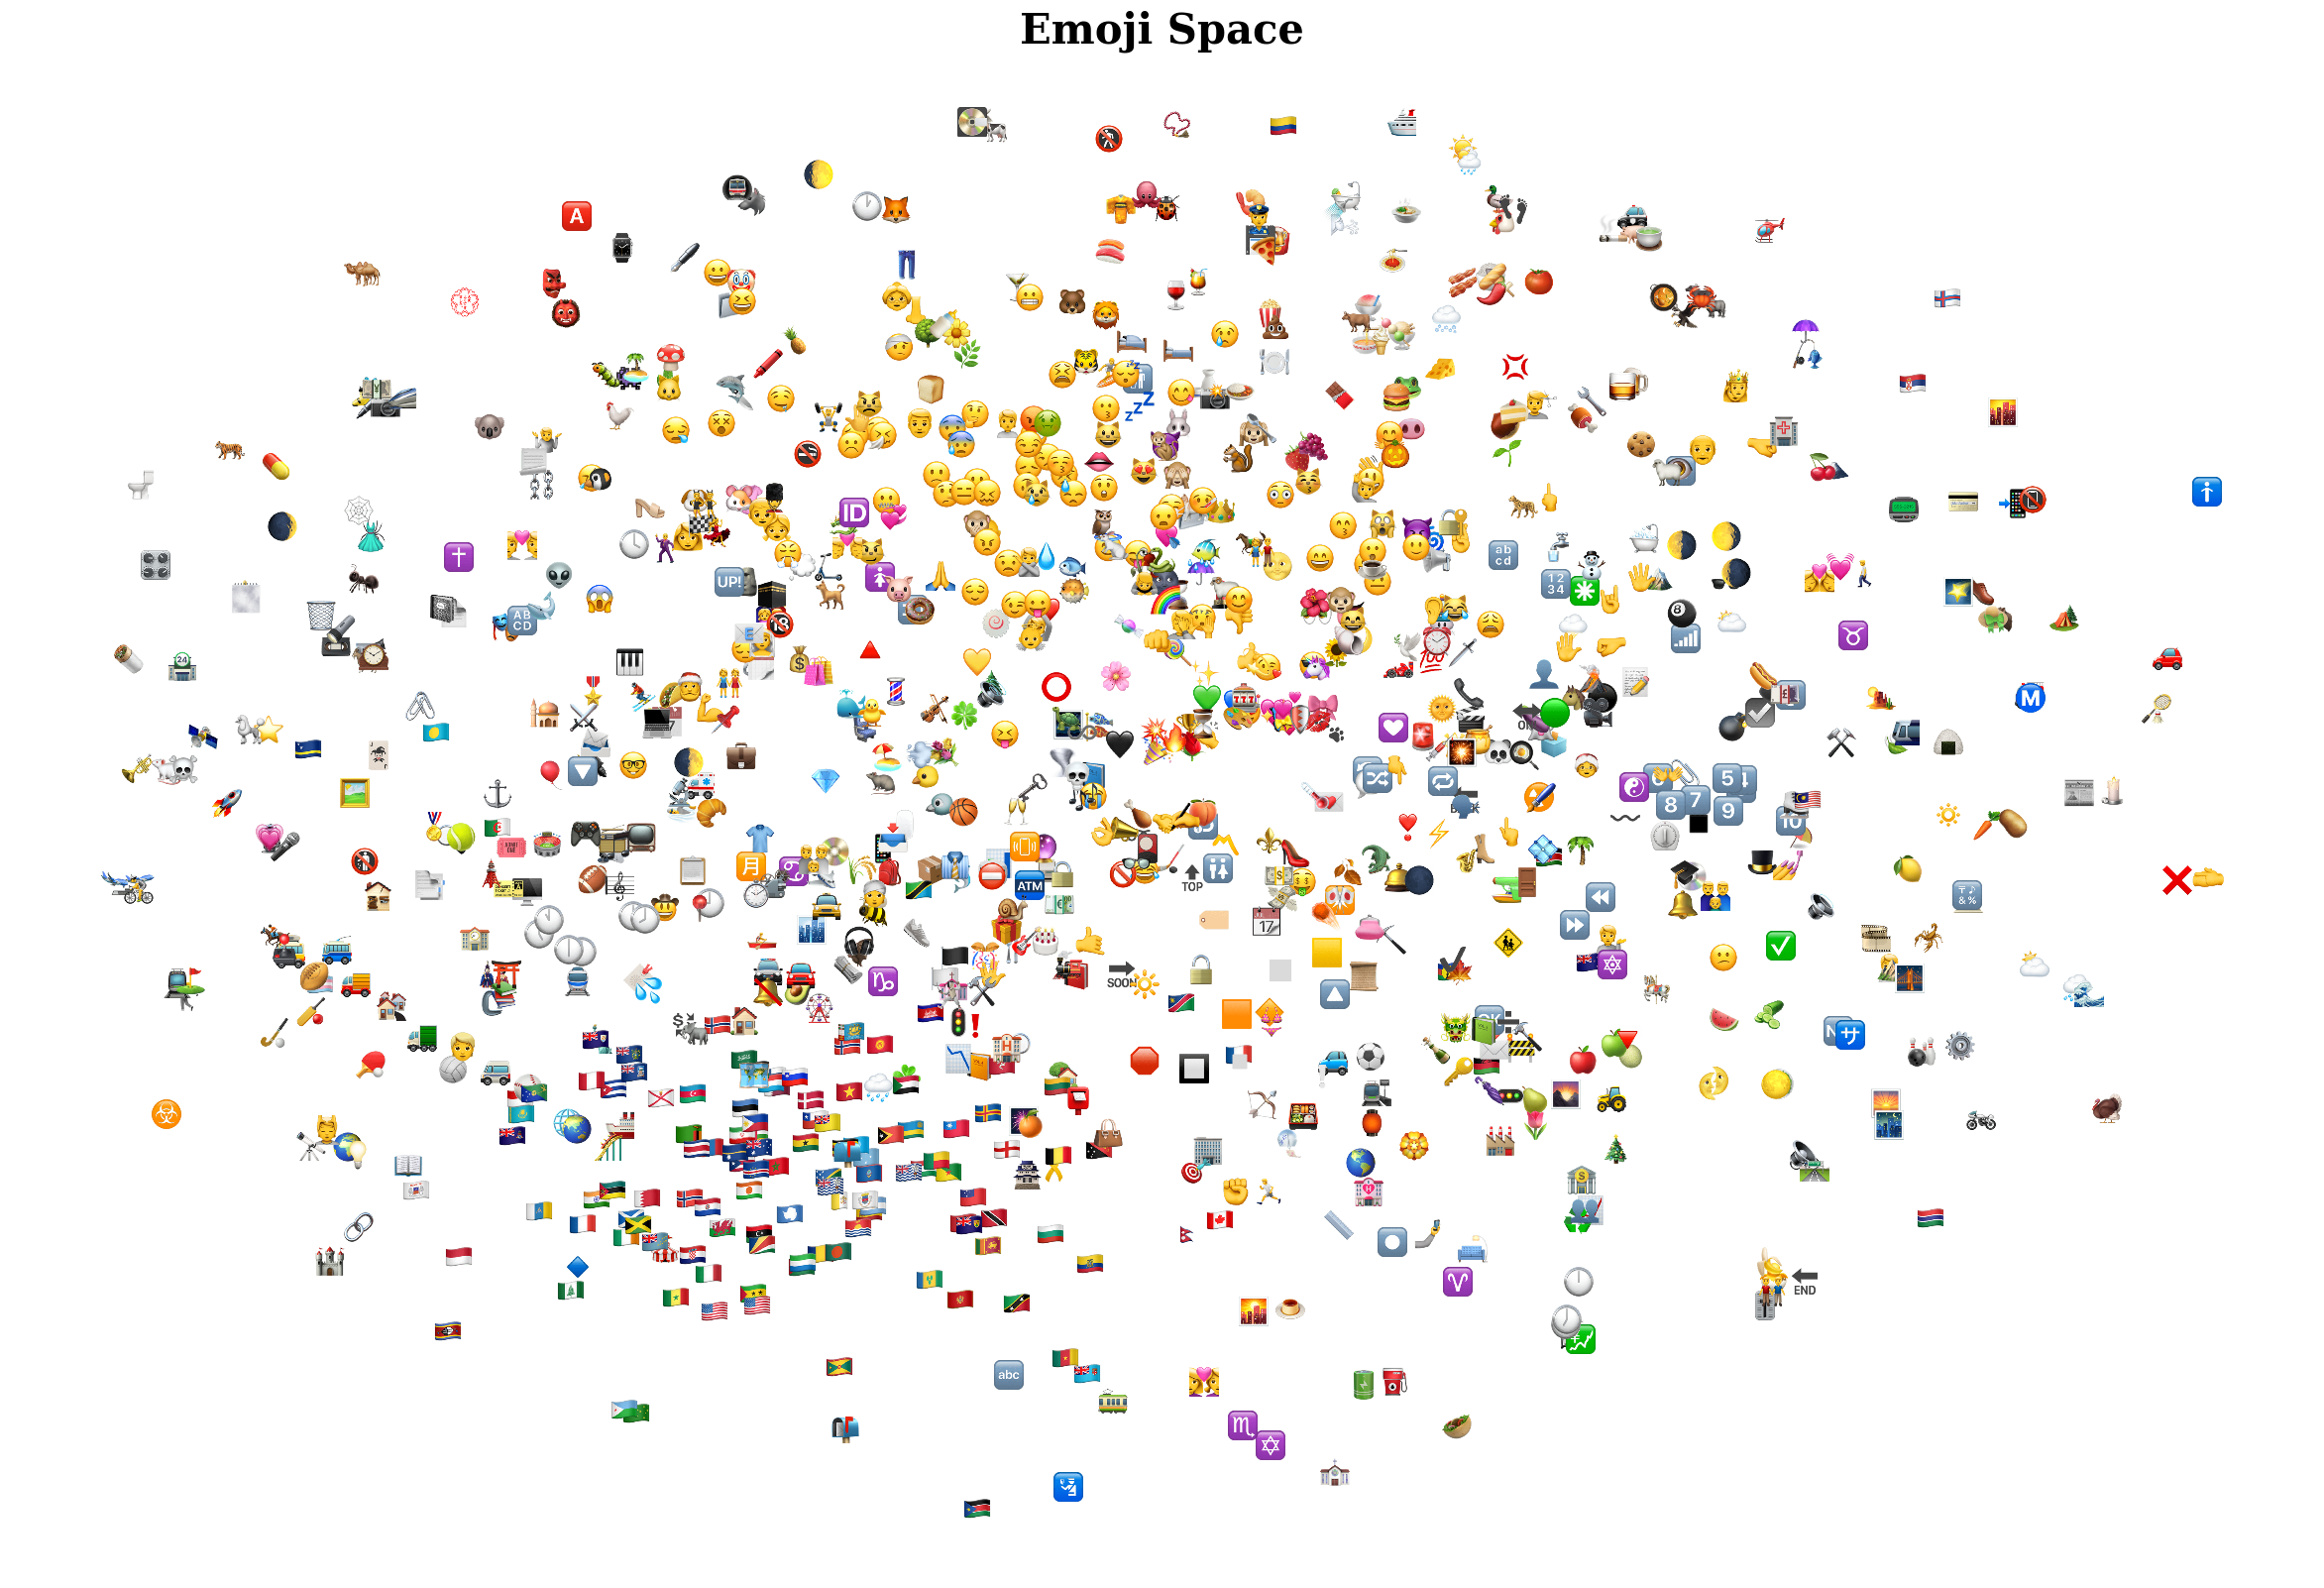
The tweet model reached 79% validation accuracy with 0.39 log loss after 80 epochs. Its clusters were less tidy, but its mistakes were often revealing: the model associated 💀 with strong emotional reactions and 🚀 with money, reflecting phrases such as “I’m dead” and “to the moon.”
| Query | Description model | Tweet model |
|---|---|---|
| 💀 | ☠️ 🆎 🌫️ 🐁 ⛓️ | 😭 🍆 😓 🤤 💔 |
| 🚀 | 🛰️ 👽 🚡 🛳️ 📡 | 💸 🔹 💯 🎯 💵 |
| lit | 🚨 🕎 🌆 🔦 📭 | 🔥 🚨 😍 ✅ 😎 |
| bitcoin | 💛 🤑 🎮 💙 🌈 | 💵 🎉 😱 💸 🤑 |
Selected nearest neighbors. Description embeddings tend toward literal appearance; tweet embeddings more often reflect usage and slang. Tweet-model neighbors are restricted to the 200 most common emojis, which had the strongest training coverage.
Limits and next steps
The tweet experiment was constrained by Colab memory and compute. Only a subset of the available data was cleaned, training sampled at most 500 tweets per emoji, and only about 400 emojis had more than 50 associated tweets. Random negative sampling could also occasionally treat a valid context as a mismatch. More data, longer training, and a richer architecture would make the comparison more conclusive.
A promising extension would initialize the contextual model with the description embeddings. That would preserve a strong literal baseline while letting frequent real-world usage move each emoji toward its evolving social meaning.